Sakana Fugu is a June 2026 orchestration model from Japan's Sakana AI: one OpenAI-compatible API that routes tasks across GPT-5.5, Gemini, and Claude Opus 4.8. It posts frontier coding scores, but it is a router, not a single model, and trails Fable 5 on the hardest benchmarks.
Sakana Fugu is not a single large language model, even though it is benchmarked like one and pitched as a rival to Anthropic's Fable 5. It is an orchestration model: a learned coordinator that takes your request through one OpenAI-compatible API and routes it across a pool of existing frontier models, currently GPT-5.5, Gemini 3.5 Flash, and Claude Opus 4.8, then combines their work into a single answer. It launched on June 22, 2026 from Sakana AI, the Tokyo lab co-founded by David Ha and Llion Jones, one of the authors of the original Transformer paper.
Fugu builds on two of Sakana's ICLR 2026 papers: Trinity, a small evolved coordinator of around 0.6B parameters, and Conductor, a roughly 7B reinforcement-learning model that discovers coordination strategies and can call instances of itself recursively. It ships in two variants behind one endpoint: Fugu, tuned for speed and able to opt out of specific providers for compliance, and Fugu Ultra, tuned for maximum accuracy on hard multi-step tasks. The launch landed ten days after US export controls cut most of the world off from Fable 5 and Mythos Preview, and Sakana's framing is explicit: frontier-level results without depending on a single vendor or jurisdiction. This review separates what Fugu genuinely does well from the parts of that pitch that do not hold up.
Sakana Fugu at a glance, June 2026
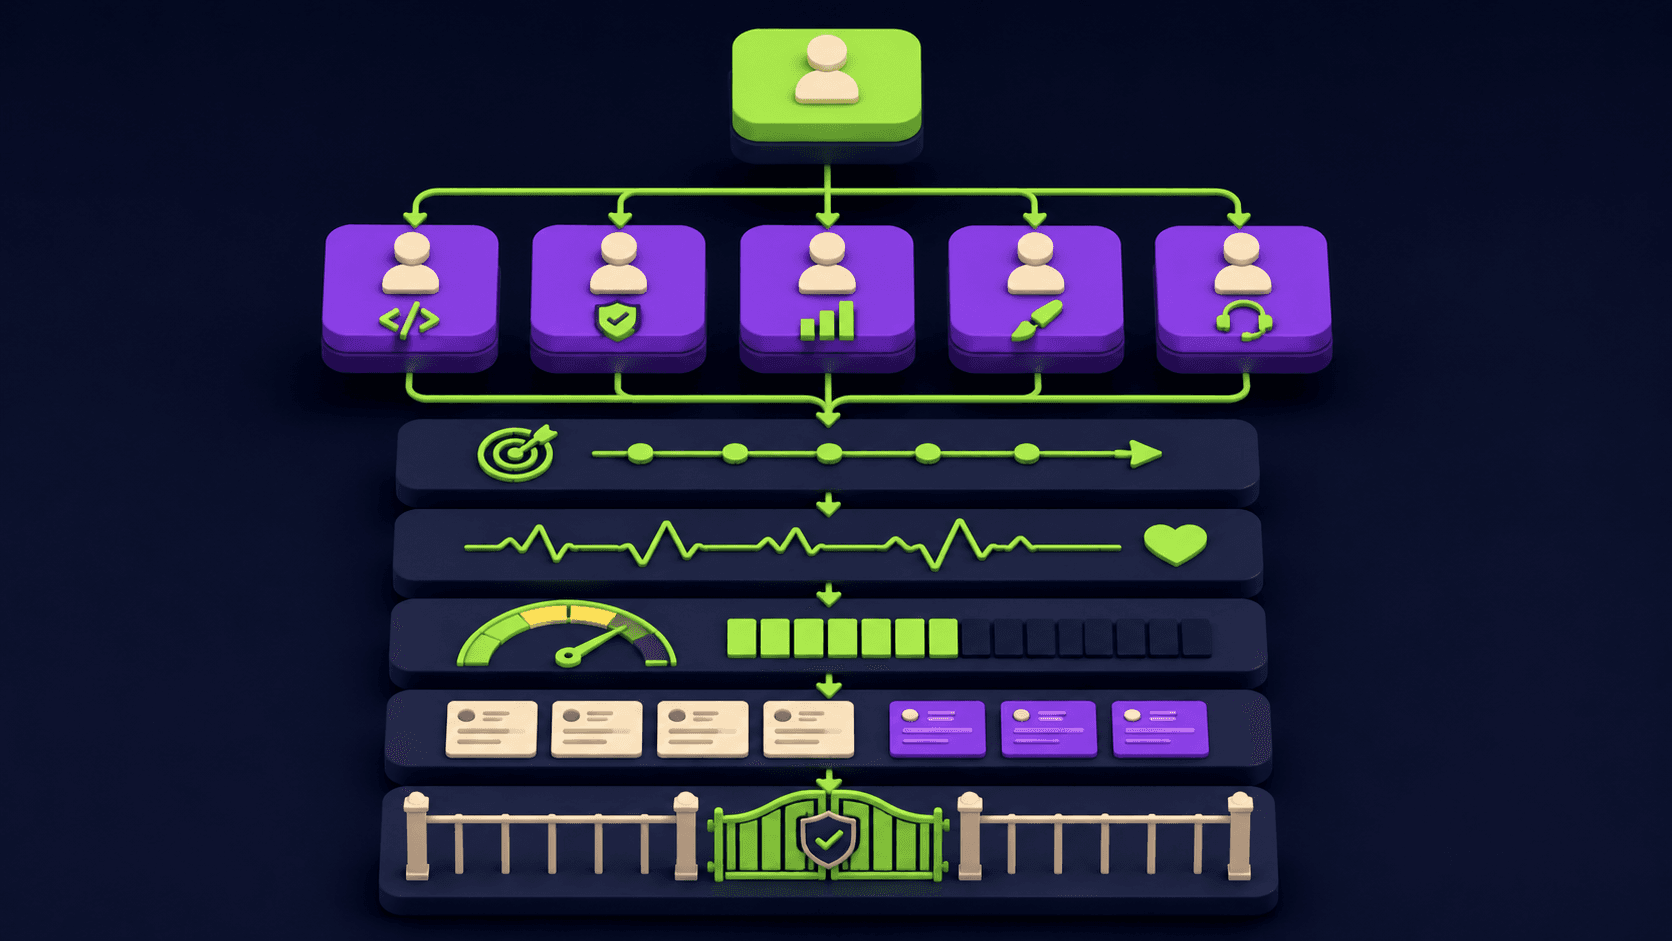
Fugu is, in Sakana's own words, "itself an LLM, trained to call various LLMs in an agent pool, including instances of itself recursively." You send a prompt to an OpenAI-compatible endpoint at console.sakana.ai, and the coordinator decides which specialist in the pool should handle each step, assigning Thinker, Worker, or Verifier roles across turns, before returning one combined response. There is a published technical report on arXiv (2606.21228) behind it, which is more transparency than most product launches offer.

Two variants are available. Fugu is the speed-and-cost default and lets you exclude specific providers, useful if your compliance rules bar a given vendor. Fugu Ultra (model ID fugu-ultra-20260615) uses a fixed pool tuned for accuracy. Sakana lists case studies spanning automated research, classical Japanese reading-order prediction, a Rubik's Cube solver, CAD mechanical-iris design, blindfold chess, and equity-trading decisions. One practical limit at launch: Fugu is available globally except the EU and EEA, where GDPR compliance was still pending as of June 22, 2026.
What Sakana Fugu is actually good at
The strongest idea here is provider independence through a single interface. Instead of hardcoding your stack to one model and rewriting prompts when that model changes or becomes unavailable, you call Fugu and let the coordinator pick. For an organization rattled by the June 12 export controls that made Fable 5 and Mythos inaccessible overnight, that resilience pitch is real and timely. CEO David Ha framed it directly:
"Relying on a single company's APIs for critical infrastructure, finance, or governance is a material vulnerability. This risk is no longer a hypothetical possibility, but a reality." (David Ha, Sakana AI CEO, June 2026)
On raw numbers, Fugu Ultra does post frontier-level scores on parts of the suite. It leads on LiveCodeBench (93.2) and edges ahead on GPQA-Diamond (95.5), and Sakana reports it outscoring Opus 4.8, GPT-5.5, and Gemini 3.1 Pro on several coding benchmarks. The recursive, role-based orchestration is genuinely novel work from a credible lab, and the arXiv report makes the method inspectable rather than a black box.
The Fable 5 comparison: what the benchmarks really show
Sakana states that "Fugu Ultra stands shoulder-to-shoulder with leading models like Fable 5 and Mythos Preview across the industry's most rigorous engineering, scientific, and reasoning benchmarks." That claim is real, but three things undercut it, and they matter.
First, Fable 5 and Mythos are not in Fugu's pool. They are export-controlled, so Fugu cannot access them, and the comparison uses Anthropic's own published numbers rather than a controlled head-to-head run. Second, no independent third party has yet reproduced the results. Third, the numbers are mixed once you look past the coding wins.

| Benchmark | Fugu Ultra | Fable 5 / Mythos | Edge |
|---|---|---|---|
| LiveCodeBench | 93.2 | 89.8 (Fable 5) | Fugu by 3.4 |
| GPQA-Diamond | 95.5 | 94.1 (Mythos) | Fugu by 1.4 |
| SWE-Bench Pro | 73.7 | 80.0 (Fable 5) | Anthropic by 6.3 |
| TerminalBench 2.1 | 82.1 | 88.0 (Mythos) | Anthropic by 5.9 |
| Humanity's Last Exam | 50.0 | 53.3 (Fable 5) | Anthropic by 3.3 |
The honest read: Fugu Ultra wins on LiveCodeBench and GPQA-Diamond and trails on the highest-stakes tests, SWE-Bench Pro, TerminalBench, and Humanity's Last Exam. "Comparable to Fable 5" is selective parity on a few benchmarks, not across-the-board equivalence, and it is provider-reported rather than independently verified. Treat the headline as marketing, and the table as the reality.
Where Sakana Fugu breaks: the failure modes users report
Early hands-on reactions were mostly skeptical, and they cluster on three issues: speed, cost, and the question of whether orchestration adds enough value to justify the layer. On Hacker News:
"For $200/month you get less than 3 hours of use per week, the API is extremely slow, and the output quality in my tests is nowhere near Fable." (cortesi, Hacker News, June 2026)
The most common structural criticism is that Fugu is a paid router on top of models you already pay for, which can mean paying three providers plus Sakana to coordinate them. A reviewer summarized the mood bluntly:
"Until proven otherwise, this is just a highly advanced router or wrapper, not a fundamental leap in intelligence like Mythos or Fable was." (GreedyWorking1499, Reddit, June 2026)
Two more caveats are worth weighing. The vendor-independence pitch is partly hollow, because Fugu still routes through US-controlled frontier models (Opus, GPT, Gemini), so it reduces single-vendor dependence rather than eliminating geopolitical exposure. And Sakana carries a credibility cloud: its 2025 "AI CUDA Engineer" claimed large kernel speedups that were quickly traced to an evaluation-sandbox loophole, which is why parts of the community want independent verification before trusting Fugu's headline numbers. Add the EU unavailability and the slow API, and this is a launch to evaluate carefully, not adopt on faith.
Sakana Fugu vs. a single frontier model
The cleanest way to think about Fugu is that it is a system for deciding how multiple model choices get used, while Claude (Opus and Fable), ChatGPT (GPT-5.5), and Google Gemini are single model choices with a clear identity. That difference cuts both ways. Routing can lift results on complex, multi-step work where different models have different strengths, and it gives you one endpoint to maintain instead of three integrations. But it also adds latency, adds a layer of cost, and reduces visibility into which model actually produced your output, which matters for reproducibility, debugging, and compliance.
So Fugu is not a one-to-one substitute for Fable 5. If you need a known, premium model with a stable identity and the best score on the hardest agentic-coding benchmarks, a single frontier model still wins. If you want provider-agnostic access and are willing to trade some control and speed for it, Fugu is the more interesting option. The two are solving different problems, despite the benchmark framing that puts them head to head.
Sakana Fugu pricing
Access is through subscriptions or pay-as-you-go tokens. Subscriptions are Standard at $20 a month, Pro at $100 a month (about ten times the Standard allowance), and Max at $200 a month (about thirty times Standard). Pay-as-you-go pricing for Fugu Ultra is $5 per million input tokens and $30 per million output tokens, rising to $10 and $45 for context above 272K, with cached input at $0.50 per million. Sakana is running a free second month for subscriptions started before July 31, 2026. Note that token costs reflect orchestration overhead, since a single request can fan out across several underlying models, so real-world spend can run higher than the headline rate suggests on multi-step tasks.
Who should use Sakana Fugu, and who should wait
Fugu is worth a serious look if you are a developer or platform team that wants one provider-agnostic API across frontier models, an organization worried about vendor lock-in or export-control exposure after the June 12 restrictions, or a team doing complex multi-step coding and research work where routing across specialists can help. The OpenAI-compatible endpoint makes a trial low-friction if you already build against that interface.
Wait or look elsewhere if you need a proven single model with a stable identity and top scores on agentic-coding benchmarks, where Fable 5 or Opus 4.8 still lead, if you are cost or latency sensitive, if you are in the EU where it is not yet available, or if you want independently verified frontier reasoning rather than provider-reported claims from a brand-new product. Fugu is one of the most genuinely novel launches of mid-2026, but it is also unproven in the field, and the smart move today is to test it against your own workload rather than trust the Fable 5 headline.
User Reviews
No reviews yet. Be the first to share your experience!
Sign in to write a review.
Related articles
Guides and articles related to Sakana Fugu.

Grok 4.3 API for Agents (May 2026): Pricing, Benchmarks, Migration
The Personal AI Productivity Stack (2026): One Tool Per Job, Nothing Extra
DeepSeek V4 Pro vs Claude Opus 4.7: 5-PR Refactor Test (2026)
What People Are Building With Claude Fable 5 (And Which Viral Demos Are Fake)
Claude Code vs Cursor vs Codex vs Devin vs Replit Agent 3: 2026 Scorecard