Crusoe Cloud is a renewable-energy GPU cloud for AI training and inference, running H100, H200, and AMD MI300X clusters. Trusted by Windsurf and Decart, with 99.98% uptime SLAs and reserved capacity starting around $3.90/hr for H100.
Crusoe is an AI infrastructure company that operates GPU cloud clusters powered by renewable and stranded energy sources. Founded in 2018 by Chase Lochmiller and Cully Cavness, the company started by capturing flared natural gas at oil fields and converting it into electricity for modular data centers. After the ChatGPT-driven explosion in AI compute demand, Crusoe pivoted fully to AI cloud infrastructure, divesting its original Digital Flare Mitigation and Bitcoin mining division to NYDIG in March 2025. The company closed a $686M Series D in December 2024 at a $2.8B valuation, led by Founders Fund with NVIDIA, Fidelity, and Mubadala participating. By October 2025, Crusoe's valuation reached $10B following a $1.375B Series E.
Crusoe Cloud runs NVIDIA H100, H200, B200, and GB200 NVL72 clusters alongside AMD MI300X hardware, covering training, fine-tuning, and inference workloads. On-demand pricing is available for H100 ($3.90/hr), H200 ($4.29/hr), and MI300X ($3.45/hr), with reserved capacity contracts offering deeper discounts for sustained workloads. The platform is used by Windsurf (formerly Codeium), Decart, BosonAI, Pixelcut, and Together AI. Crusoe is also the lead developer of the Stargate flagship campus in Abilene, Texas, a $500 billion AI infrastructure initiative backed by OpenAI, Oracle, and SoftBank that went live in September 2025.
What Crusoe actually does in May 2026
Crusoe Cloud provides bare-metal and virtual GPU clusters for AI workloads. You pick a GPU type, provision a node or cluster via the web console or API, and run your containerized training or inference stack on top. There is no managed layer, no pre-built ML environment, and no experiment tracking built in. The platform handles hardware reliability, networking, and power; your team handles everything above the OS.
Current GPU lineup on-demand:
NVIDIA H100 SXM 80GB: $3.90/hr on-demand
NVIDIA H200 HGX 141GB: $4.29/hr on-demand
AMD MI300X 192GB: $3.45/hr on-demand
NVIDIA B200 / GB200 NVL72: contact sales
NVIDIA A100 SXM 80GB: $1.95/hr on-demand, $1.30/hr spot
NVIDIA L40S 48GB: $1.00/hr on-demand, $0.50/hr spot
Reserved capacity contracts allow teams to lock in specific GPU volumes for defined periods at deeper discounts. These require a sales conversation; there is no self-serve commitment tier. The API follows standard REST conventions and integrates with Kubernetes-based orchestration layers, though teams must bring their own container infrastructure and orchestration tooling.
Crusoe's energy sourcing sets it apart from every other GPU cloud. Data centers run on captured stranded natural gas (via its Digital Flare Mitigation technology, which has repurposed over 21 billion cubic feet of stranded gas since 2018), behind-the-meter renewables, and hybrid wind/solar campuses. The Abilene, Texas flagship campus runs at 1.2GW. Iceland and Norway expansions are underway. This energy story is auditable, not marketing: Crusoe publishes its avoided emissions and CO2 figures publicly.
"Codeium's NVIDIA H100 Tensor Core GPUs on Crusoe have been incredibly reliable with a cluster uptime of 99.98%." - Varun Mohan, Co-Founder and CEO, Windsurf (formerly Codeium), December 2024
Where Crusoe sits versus CoreWeave and Lambda Labs
The GPU cloud market has three distinct tiers. CoreWeave occupies the hyperscale enterprise position, Lambda Labs serves research teams and growth-stage startups with simpler self-serve access, and Crusoe sits between them: larger scale and better reserved-capacity guarantees than Lambda, with lower H100 pricing than CoreWeave's published on-demand rates, and an energy differentiation neither competitor offers.
CoreWeave operates 32+ data centers across the US and Europe with approximately 250,000 GPUs deployed. Its $65B post-IPO valuation (March 2025) reflects that it holds long-term hyperscale contracts with Microsoft (for OpenAI's compute), Meta, and Cohere. CoreWeave runs Kubernetes-native infrastructure, which suits teams already running K8s workloads. H100 pricing starts around $4.25/hr GPU-only, or approximately $6.15/GPU when bundled in full HGX nodes with CPU/RAM. CoreWeave offers up to 60% discounts on committed annual contracts, but minimum contract sizes skew large. Crusoe has a larger total GPU pipeline (946K GPUs, 3.4GW) concentrated in fewer but bigger facilities, and its on-demand H100 rate of $3.90/hr undercuts CoreWeave's published GPU-only rate. For teams that care about sustainability credentials, Crusoe has a published energy story; CoreWeave does not market one.
Lambda Labs lists H100 SXM on-demand at $3.29/hr, an 18.5% advantage over Crusoe's $3.90/hr for the same chip class. Lambda also includes pre-installed ML frameworks (PyTorch, TensorFlow, CUDA drivers) in its VM images, making it faster to get started for small experiments. The tradeoff: Lambda H100 and H200 frequently have waitlists because the company's available inventory is smaller. Crusoe's reserved capacity model guarantees GPU availability for teams that can commit to volume. Lambda is also better suited to individual developers or teams running smaller, single-node jobs. Crusoe's architecture is designed for multi-node training clusters and sustained high-utilization workloads. If your team plans to run a 70B parameter model training run for 30 days, Crusoe's guarantee and pricing structure is more appropriate. If you need a single H100 node for two days of experimentation, Lambda's self-serve model is simpler. For teams exploring RunPod or Modal as entry points, those platforms offer even more accessible self-serve GPU access with per-second billing and managed inference layers that Crusoe does not provide.
"With Crusoe, we scaled our capacity five times within hours to serve all of our Oasis users across Europe." - Dean Leitersdorf, CEO and Co-Founder, Decart, Series D announcement, December 12, 2024
What running workloads on Crusoe actually looks like
Crusoe is raw infrastructure. You bring your own containerized stack. The onboarding path for a typical AI training team looks like this: contact sales for reserved capacity, negotiate a node count and commitment period, receive API credentials, provision nodes via the Crusoe console or REST API, then deploy your training container with your own orchestration (Kubernetes, SLURM, or custom scripts). Crusoe handles hardware failures, networking fabric, and power continuity. Your team handles everything from the OS upward.
Support quality is a genuine strength. Crusoe publishes its own customer success metrics: average first response time of 6 minutes, 100% customer satisfaction score since June 2024, average time to resolution of 23.6 hours. For a GPU cloud, where a hung node can stall a multi-day training run, that response time matters. The Pixelcut team noted: "All of our in-house machine learning models have been trained on Crusoe Cloud" - an endorsement of reliability for production ML, not just evaluation use.
The AMD MI300X option at $3.45/hr is worth noting for memory-bandwidth-intensive workloads. MI300X has 192GB of HBM3 memory per card, versus H100's 80GB, which matters for serving large context windows or running very large models without model parallelism. Teams benchmarking inference cost-per-token on long-context jobs have found MI300X competitive with H100 at lower hourly rates, particularly with JAX or ROCm-native frameworks. The tradeoff is a smaller community and fewer Crusoe-specific tutorials for ROCm compared to the CUDA ecosystem.
For teams using related tools, Crusoe clusters work well alongside Together AI for managed inference endpoints, since you can use Crusoe for training and Together AI's inference API for production serving without maintaining your own serving infrastructure. Teams that run Lambda Labs for small experiments often move reserved workloads to Crusoe when they hit Lambda's waitlist constraints. The combination is common enough that it reflects a real pattern in the market: use a simpler platform for exploration, then commit to Crusoe when workloads become predictable enough to reserve capacity.
The Crusoe console is functional rather than polished. Provisioning nodes and managing SSH key access takes a few minutes for engineers familiar with cloud infra workflows. The REST API covers the same operations and integrates well with Terraform for teams managing infrastructure as code. Monitoring is available but does not approach the depth of AWS CloudWatch or GCP's operations suite; teams running production inference typically supplement with their own Prometheus or Datadog integration.
Who Crusoe is built for
Crusoe is the right choice for teams with these characteristics: sustained, high-utilization GPU workloads (training runs measured in days or weeks, not hours); a need for guaranteed cluster availability rather than best-effort on-demand; infrastructure engineers who can manage their own containerized stack; and organizations with sustainability or ESG reporting requirements that make clean-energy compute credentials valuable.
Named customers span a specific profile: Windsurf (formerly Codeium, 700K+ developer users), Decart (viral product launches requiring rapid scale), BosonAI (LLM training at scale), Pixelcut (production ML in consumer apps), and Oaklet (real-time record processing via Crusoe Managed Inference). These are not hobbyist users. They are teams with dedicated infrastructure engineers running production AI services.
The Stargate role is a signal about trajectory. Being named as the lead developer for OpenAI's flagship compute campus is not a marketing claim. It reflects that Crusoe can deliver at a scale and reliability level that OpenAI, Oracle, and SoftBank signed contracts for. For enterprises making multi-year GPU infrastructure decisions, that provenance carries weight.
What Crusoe is not
Crusoe is not a self-serve GPU rental platform for individual developers. There is no credit card signup, no per-second billing, no free tier, and no one-click Jupyter notebook environment. If you are a solo researcher who needs a single H100 for a two-day experiment, Lambda Labs or RunPod will get you started in minutes; Crusoe will ask you to talk to sales first.
Crusoe does not include managed ML infrastructure. There is no built-in experiment tracking, no model registry, no automated hyperparameter search, and no managed serving layer. Teams that have been using Google Vertex AI or AWS SageMaker will find Crusoe more like renting a server than like using a cloud AI platform. You own the full stack from OS upward.
Geographic coverage is a real limitation in early 2026. Most Crusoe GPU capacity is US-based (primarily Texas). Iceland expansion is underway; Europe is early-stage. Teams with EU data residency requirements or latency-sensitive European inference workloads will find options limited compared to AWS or CoreWeave's European footprint. For managed inference APIs that run globally without this geographic constraint, Together AI or Modal are better options. Burst and sporadic workloads, where GPU utilization swings from near-zero to peak and back, are a poor fit for Crusoe's pricing model. The hourly rate is constant whether the GPU is saturated or idle.
User Reviews
No reviews yet. Be the first to share your experience!
Sign in to write a review.
Related articles
Guides and articles related to Crusoe.

Grok 4.3 API for Agents (May 2026): Pricing, Benchmarks, Migration

Does API Cost More Than a Subscription for Claude Opus 4.8, GPT-5.5, and Grok?

Mistral Medium 3.5 Self Host: 77.6% SWE-Bench on 4 GPUs (2026)

Replit Pricing Explained (2026): Core vs Pro and Effort-Based Agent Billing
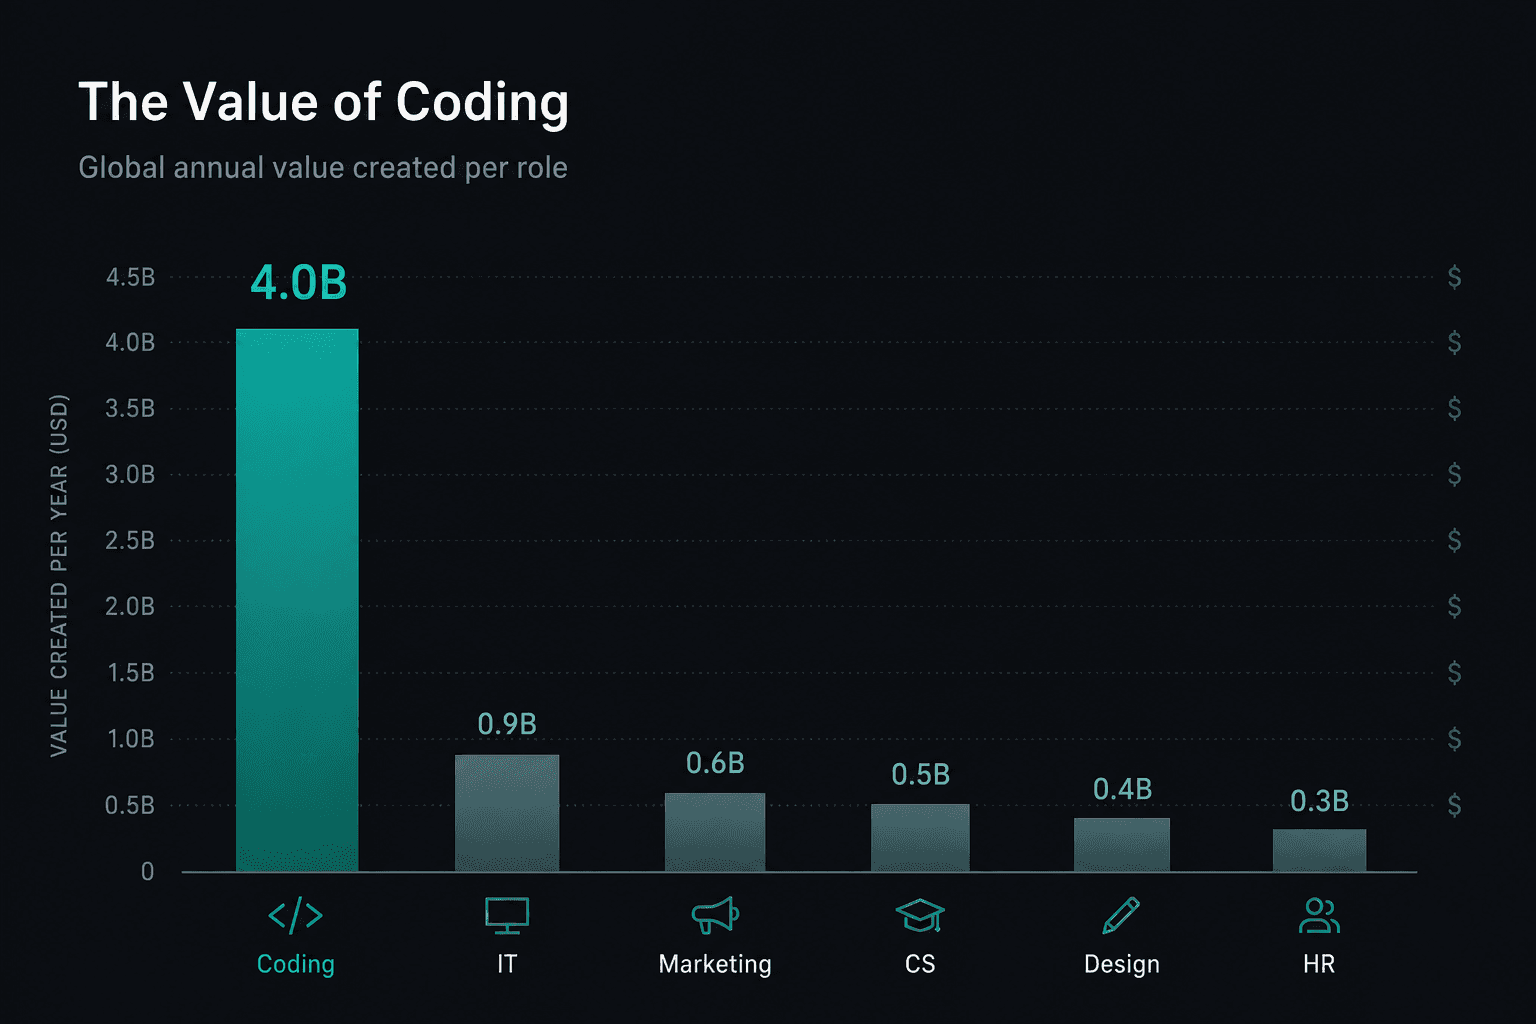
Coding Ate Enterprise AI (2026): The $4B Use Case, Anthropic’s Share, and Seat vs API Math