Stagehand is an MIT-licensed TypeScript SDK from Browserbase that adds natural-language browser control (act, extract, observe) on top of CDP, letting developers build browser agents that survive UI changes without selector maintenance.
Stagehand is an open-source browser automation SDK built by Browserbase that bridges the gap between brittle CSS-selector scripts and unpredictable fully-autonomous agents. Released in October 2024 and now at v3, it gives TypeScript and Python developers three composable primitives, act(), extract(), and observe(), plus an autonomous agent() mode, each backed by the LLM of your choice. Where a traditional Playwright script hardcodes page.click('#submit-btn') and breaks the moment a designer renames a class, Stagehand resolves act("click the submit button") against the live DOM at runtime, so the script survives quarterly UI refreshes with zero maintenance.
The framework is MIT-licensed and free to run locally against any Chromium instance. It pairs with Browserbase's managed cloud runtime (optional, paid) for residential proxies, stealth browsing, CAPTCHA solving, and session recording. Stagehand supports OpenAI, Anthropic Claude, and Google Gemini via the Vercel AI SDK, and v3's direct Chrome DevTools Protocol (CDP) architecture makes it model-agnostic and driver-agnostic. As of April 2026, the GitHub repository sits at 22,400 stars, 1,500 forks, and 57 releases, with a Python port shipping alongside Browserbase's $40M Series B in June 2025.
What Stagehand actually does in April 2026
Stagehand v3, released October 29, 2025, removed the Playwright hard dependency entirely and rebuilt the framework on direct CDP communication. The architecture change was significant: Stagehand no longer inherits Playwright's testing-first assumptions, and it supports Puppeteer, Playwright, Bun, or any other CDP-compatible driver as a modular backend. On iframes and shadow-root interactions, where selector-based tools struggle most, v3 is 44.11% faster than v2.
The four primitives each do a distinct job. act() performs browser actions from plain English ("click the next page button," "fill the email field with [email protected]"). extract() pulls structured data from a page and validates it against a Zod schema, so you get typed objects back rather than raw HTML. observe() surfaces what interactive elements exist on a page before you commit to an action, useful for conditional logic and safety checks. agent(), added in v2, runs multi-step workflows autonomously when you want end-to-end execution without orchestrating each step manually.
V3 also introduced a context builder that feeds models only the relevant DOM subset per action, rather than dumping the full page. This reduces token waste substantially and makes the per-action cost more predictable. Server-side caching, added in v3.1.0 (February 2026), stores act/extract/observe results so repeated runs through the same flow skip LLM inference entirely once the workflow stabilizes.
"Our Stagehand v3 workflows are noticeably snappier when run side-by-side with v2. We now get detailed observability and token-level reporting per action." - Steve Austin, Co-Founder and CTO at Benny, Stagehand v3 launch blog, October 2025
Model support covers GPT-4o, Claude 3.7 Sonnet, Gemini 2.0, and newer releases in each family. The team's internal finding: Claude handles reasoning-heavy steps better, GPT-4o variants execute precise actions more reliably, and Gemini suits observation tasks. The framework's model-agnostic design lets you route different primitives to different models within a single script, though most teams pick one and stay consistent.
Where Stagehand sits versus Playwright and Browser-Use
Playwright (no AI) is the baseline every AI browser automation tool competes against. It's purely deterministic: every action requires an explicit selector or role locator, zero LLM cost per action, and execution speed under 100ms per step. On stable UIs, hand-written Playwright scripts complete tasks at 92-98%. The cost of that reliability is maintenance: every major UI redesign breaks 15-25% of selectors, requiring an engineer to update scripts. Playwright has 70,000+ GitHub stars, a mature codegen tool that records sessions into scripts, and a first-class tracing and video recording ecosystem. It is the substrate that Stagehand originally wrapped and that most teams still use for the predictable 80% of their automation steps. The practical production pattern that's emerged is Playwright for deterministic navigation and login flows, Stagehand for the dynamic extraction and action steps in the middle.
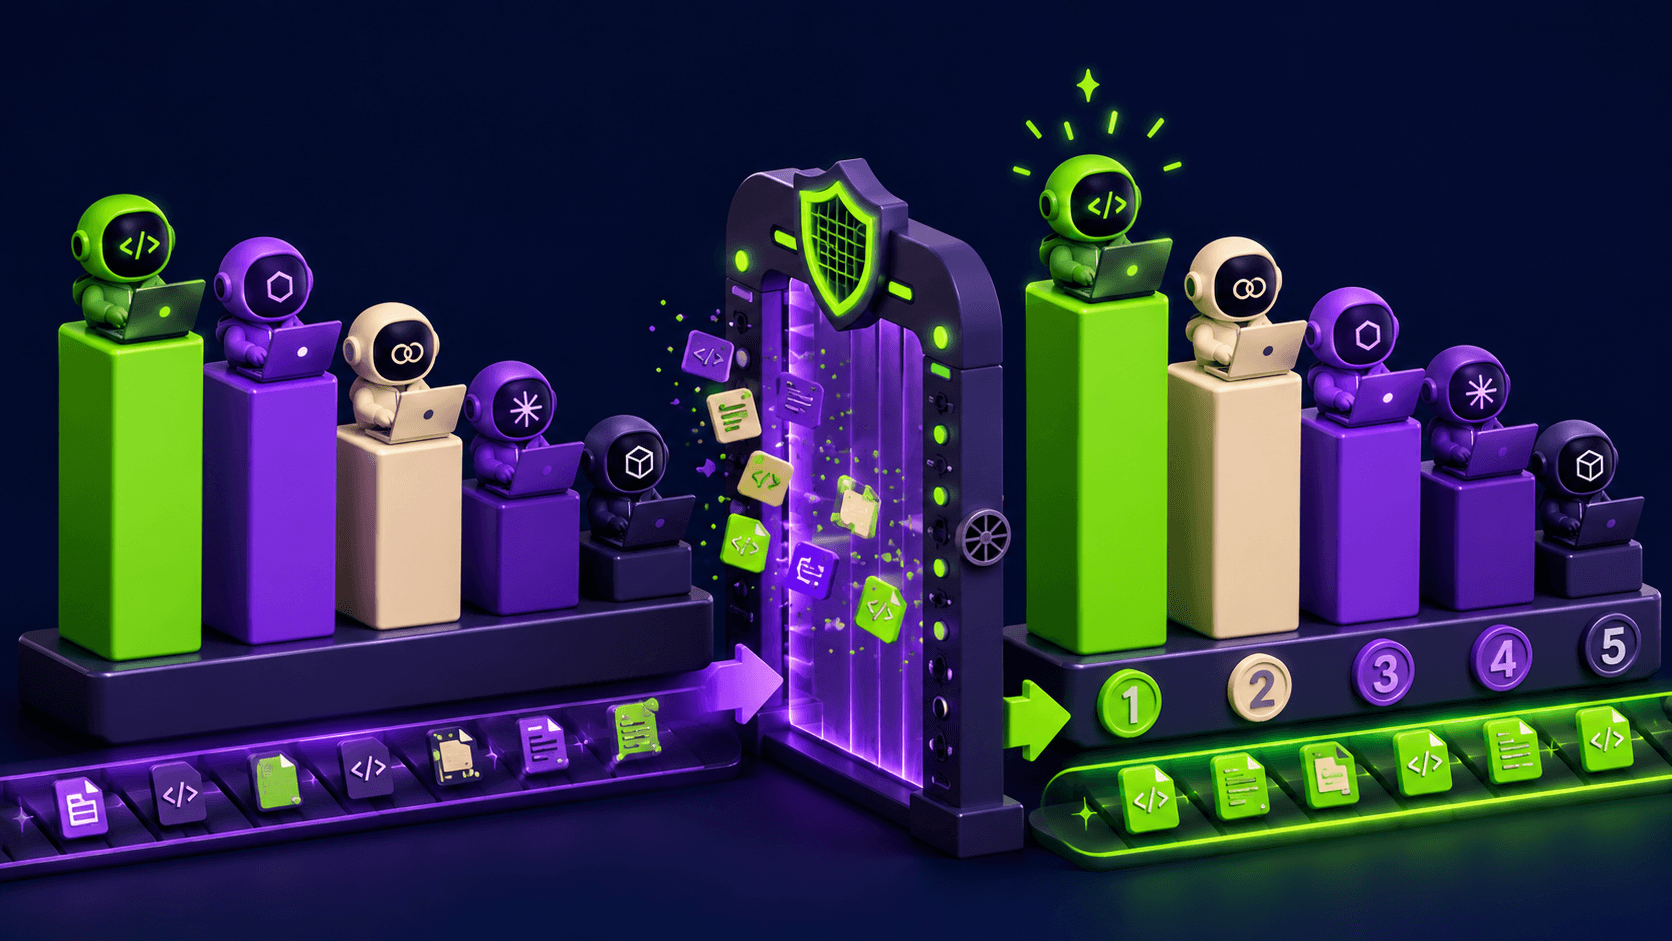
Browser-Use is the Python-first alternative with a different philosophy. Where Stagehand is hybrid (you decide which steps are AI-driven), Browser-Use runs a full autonomous agent loop where the LLM receives the page state, decides what to do next, and iterates until the goal is reached. It supports local Ollama models, which means zero inference cost for teams willing to run their own hardware. Browser-Use crossed 80,000 GitHub stars by early 2026, driven heavily by Python developers who find its simpler API more accessible. The tradeoff is predictability: Browser-Use re-reasons from scratch on every run, so the same goal can produce different execution paths on different days. Stagehand's caching model and explicit primitives make it more repeatable in production, where you need to audit what the script did and why. For exploratory, open-ended web tasks where the sequence of steps isn't fixed, Browser-Use is often the better fit. For production pipelines where you're running the same workflow 500 times a day and need reliable, debuggable execution, Stagehand wins.
A third category worth noting is AgentQL, which takes a query-language approach rather than a method-call approach. AgentQL uses a GraphQL-inspired syntax to describe page elements declaratively, while Stagehand uses imperative code with natural-language arguments. Both sit atop similar browser infrastructure, but the mental model differs significantly. Teams with strong TypeScript patterns tend to prefer Stagehand; teams who want to express data schemas as queries tend to prefer AgentQL. Stagehand's act/extract/observe API is simpler to reason about when debugging.
What the agent workflow reality looks like
Most production Stagehand setups follow a predictable pattern. The deterministic, well-understood steps (authenticate, navigate to the target page, set filters) use plain Playwright or Stagehand calls with explicit selectors. The steps where page structure varies (dynamically loaded tables, shadow-DOM components, authenticated data behind multi-step flows) call Stagehand's AI primitives. This hybrid approach keeps LLM costs manageable: at $0.002-$0.02 per act/extract call, a workflow with five AI steps costs less than $0.10 per run, which is viable. Running every single step through AI is where teams get into trouble with the math at scale.
Debugging is different from debugging pure Playwright. When an act() call fails or misinterprets an ambiguous instruction, the error surfaces as a runtime exception with the model's interpreted action logged, but reading AI decision traces is a different skill than reading a selector mismatch. The Stagehand API (released June 2026) moved some of this translation work to managed infrastructure with human-readable action logs and token-level observability per step, which directly addresses the "black box" complaint from the early HN thread.
"I don't think I could plausibly argue for using LLMs at runtime in our test suite at work. The right approach would be to use AI to help write Playwright test code, not replace the deterministic part." - mpalmer, Hacker News, January 9, 2025
This skepticism from the HN launch thread turned out to be partially right and partially wrong. For CI/CD test suites where determinism is non-negotiable, Stagehand's LLM-at-runtime approach is still a hard sell. For production automation pipelines where maintenance cost is the real enemy, the tradeoff has proven worthwhile for a significant slice of teams. The important architectural distinction is that Stagehand is primarily a browser automation tool that happens to work well in testing contexts, not a test framework with AI features added.
The real operational complexity comes when you need browser infrastructure capabilities that Stagehand doesn't provide natively. Bot detection, CAPTCHA solving, residential proxies, session recording, multi-region execution, and HIPAA-compliant data handling all require either the paid Browserbase managed runtime or substantial custom plumbing. Teams building simple internal automation can run Stagehand against a local Chromium instance and pay only their LLM API costs. Teams building production-grade web agents typically need both.
Who Stagehand is built for
TypeScript developers building browser agents for production automation are the primary audience. QA engineers who want to write tests in human-readable natural language, without committing to Playwright selector maintenance, are a strong secondary audience. Teams that already have Playwright codebases and want to augment specific steps with AI reasoning (rather than replace the entire stack) are a third segment where Stagehand integrates cleanly.
Stagehand also fits naturally into AI agent frameworks. Its act/extract/observe primitives map well to tool calls in OpenAI Agents SDK-style architectures, where a planning agent decides which web actions to take and Stagehand executes them. Teams building data pipelines that include web data alongside structured sources often combine Stagehand for extraction with tools like Firecrawl (for clean document extraction) or Apify (for scalable scraping infrastructure). Stagehand handles the authenticated, JavaScript-heavy, form-filling scenarios that static crawlers cannot reach.
The Series B milestone (June 2025) and 500,000+ weekly NPM downloads confirm that Stagehand has graduated from a promising open-source experiment to a framework with genuine production adoption and a funded team behind it. The v3 CDP architecture removes the dependency on a specific upstream (Playwright), which reduces the risk that changes to Playwright's internals break Stagehand's behavior.
What Stagehand is not
Stagehand is not a replacement for Playwright in high-volume, cost-sensitive automation. At 10,000 extractions per day, LLM fees run $50-200/day with mid-tier models, even with caching. For that volume with stable, well-understood page structures, maintaining Playwright selectors is cheaper. The break-even point where Stagehand's maintenance savings outweigh its LLM costs depends heavily on how frequently the target sites change their DOM and how expensive your engineers' time is.
Stagehand is not a local-first or privacy-first tool. It requires cloud LLM API credentials for every AI-driven step. Browser-Use's support for Ollama makes it the better choice for teams that cannot send page content to external APIs due to data residency requirements or security policy.
It is not a point-and-click no-code tool. Stagehand is a developer SDK. You write TypeScript (or Python) code. The natural language is inside method calls, not in a visual workflow builder. Teams without engineering capacity should look at Browserbase's Director.ai product (released June 2025) for a no-code browser agent interface.
It is not a complete replacement for human-supervised browsing in sensitive contexts. Financial transactions, healthcare data entry, and legal document workflows require approval steps, audit logs, and compliance tooling that Stagehand does not provide out of the box. The framework is infrastructure, not a compliance product.
Finally, Stagehand is not well-suited for exploratory, open-ended research tasks where the exact sequence of browser actions isn't known in advance. If your goal is "find the best price for X across these 12 sites" with no fixed workflow, Browser-Use's autonomous reasoning loop handles goal-directed web exploration more naturally than Stagehand's composable-primitives model. For repeatable production workflows with defined steps and measurable outcomes, Stagehand's hybrid approach pays off. For fuzzy, multi-turn research tasks, a more agentic framework may serve you better.
User Reviews
No reviews yet. Be the first to share your experience!
Sign in to write a review.
Featured in collections
Curated lists that include Stagehand.
Related articles
Guides and articles related to Stagehand.
AI User Testing in 2026: The Tools That Test Your Product While You Sleep
Run a Company With AI Agents: The Open-Source Orchestration Setup (2026)
Turn Any AI Agent Into a Superagent: The 12-Integration Stack (2026)
AI Agents for Business: What They Actually Are and 12 Things You Can Automate Today
Ship Your First MCP Server in 20 Minutes (2026)